
Frame the risk in operating terms
Container platforms concentrate deployment, secrets, networking and runtime authority. Risk often enters before the cluster through source, dependencies and build workers, then expands through broad service accounts or permissive admission. Map the path from source revision to running workload and identify every identity able to change it.
Treat the subject as an operating system rather than a product setting. The accountable owner is the platform team with application owners accountable for workload configuration. Important decisions include which images may run, which identities workloads receive, which namespaces may communicate, who can change cluster policy. Record assumptions, dependencies and accepted exceptions so a future reviewer can distinguish deliberate design from accidental exposure.
Engineer a controlled path
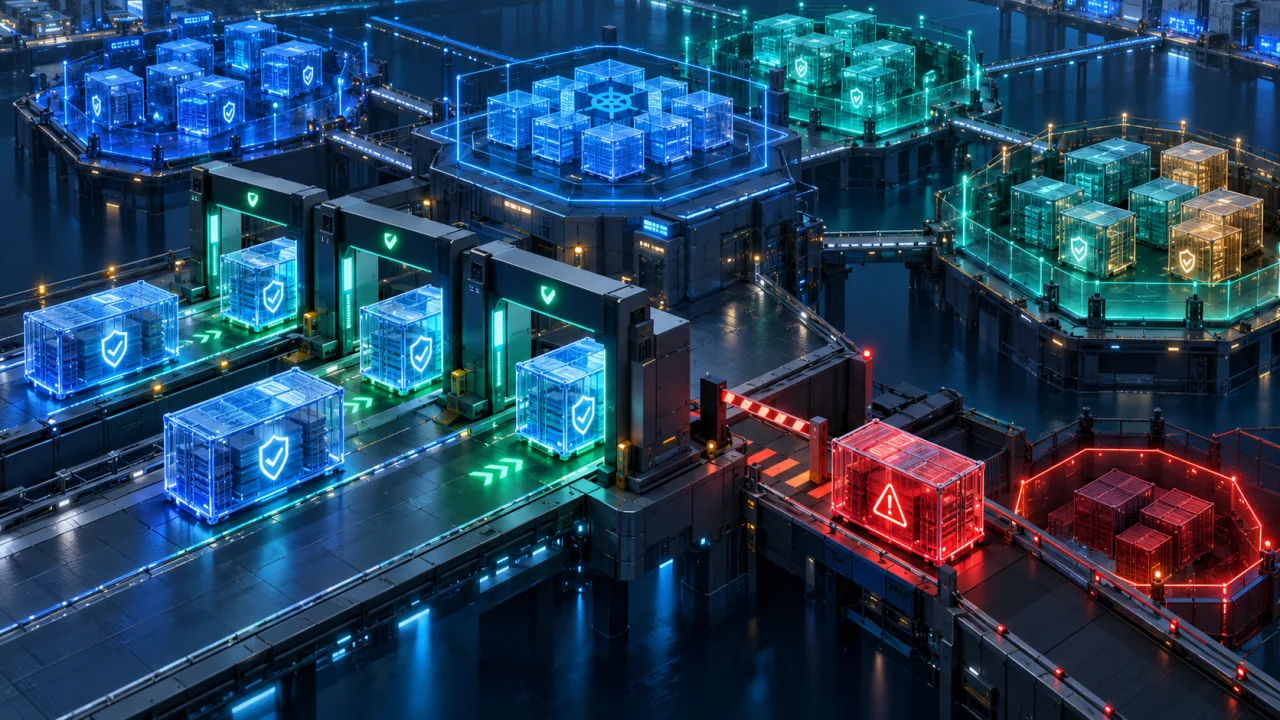
Use trusted registries, immutable image references, signed provenance where supportable and admission rules for high-risk configuration. Scope workload identities, restrict privileged containers and isolate namespaces according to required flows. Separate cluster administration from daily development and protect the policy and pipeline that enforce controls.
Build the control path in layers: trusted build provenance, admission policy, scoped workload identity, network segmentation, protected control-plane logging. Apply stronger safeguards where a failure could change production, expose sensitive information or block recovery. Pilot changes with representative users and services, define rollback criteria and make emergency access narrower and more observable than ordinary administration.
Operate from evidence, not reassurance
Inventory running images, exposed services, service accounts and policy exceptions. Monitor new privileged workloads, secret access, unusual control-plane changes and disabled enforcement. Scan is one input; patch or rebuild through the normal pipeline and verify that old vulnerable images are no longer running.
Useful evidence includes image provenance, admission decisions, service-account use, network policy tests, runtime events. Keep collection protected from the systems being observed, test that records arrive when expected and assign a person who can act on a meaningful signal. Measures such as signed or traceable workload coverage, privileged workload count, exception age, time to replace a vulnerable image should lead to a decision, not merely decorate a dashboard.
Exercise failure and improve the design
Compromise a test workload identity and determine whether it can read secrets, move between namespaces or change deployment. Practise revoking the identity, isolating the workload and rebuilding from a known source. Confirm that logs survive deletion of the affected pod and connect runtime activity to the deployed artefact.
Run a bounded exercise that forces the team to use real contacts, authority, evidence and recovery paths. Capture what was known, what was assumed and which action changed the outcome. Give every improvement an owner and validation method, then repeat the difficult part after the change instead of closing the work on written assurance.
What to do next.
- ✓Map source-to-runtime authority.
- ✓Use trusted immutable images.
- ✓Reject dangerous workload configuration.
- ✓Scope service accounts and secrets.
- ✓Segment required namespace flows.
- ✓Test containment and clean rebuild.
Use guidance responsibly
Technology, provider behaviour and legal requirements change. Validate implementation details against current official documentation, test changes safely and obtain qualified legal advice where required.