
Define the operational boundary
Policy as code can make decisions repeatable across cloud, deployment and application platforms, but an incorrect rule can also block critical services or create consistent exposure at scale. The programme needs clear ownership of both the policy intent and the technical implementation.
Document the systems, identities, information and external dependencies inside the decision. The most important failure paths are incorrect policy deployed at scale, unreviewed bypasses, schema changes altering decisions, exceptions encoded too broadly. Assign one accountable owner and record any boundary that remains outside the current work. This prevents a technically sound control from being mistaken for protection of a wider process it cannot actually cover.
Design controls around the real workflow
Express one decision per rule where practical and keep business rationale next to code. Use reviewed changes, automated tests and representative fixtures for compliant, non-compliant and exceptional resources. Separate advisory from enforced stages and define how approved exceptions are encoded without weakening unrelated systems.
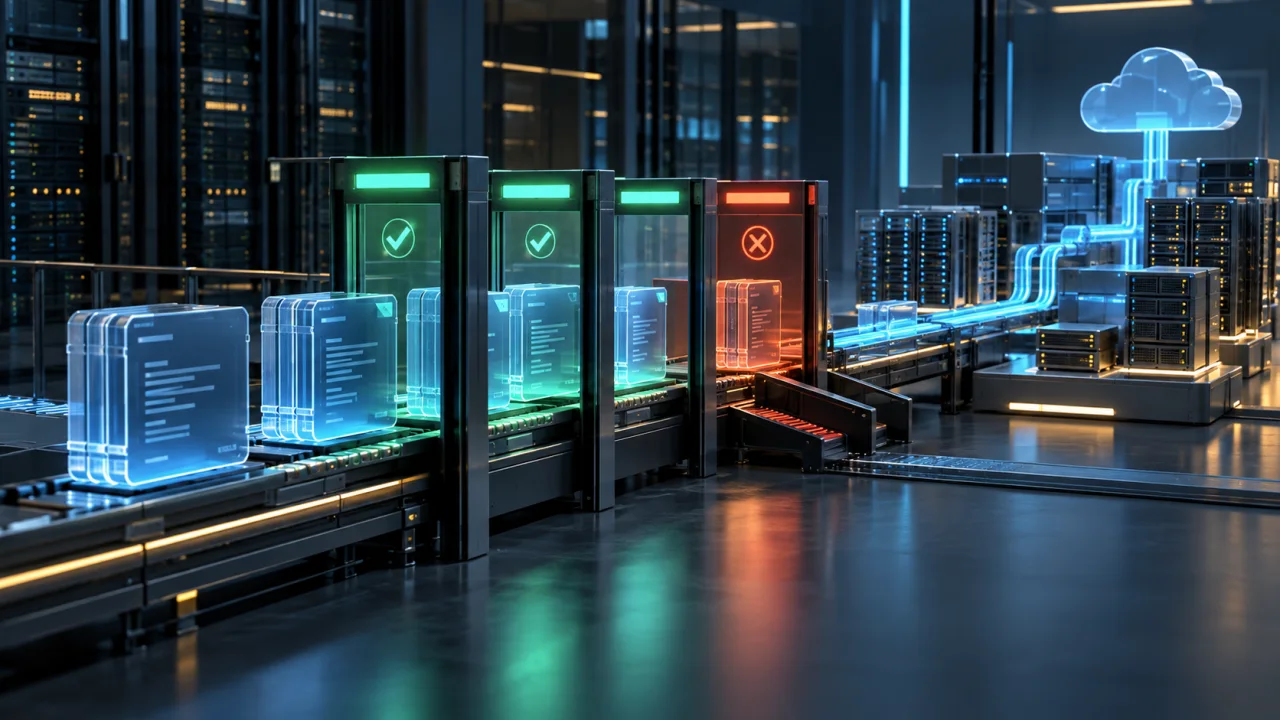
Build the control path from version-controlled policy, unit and integration tests, staged enforcement, scoped exception objects, rapid rollback. Each layer should have a stated purpose, an implementation owner and a safe failure mode. Test ordinary work as well as privileged and emergency journeys. Where the strongest option cannot yet be used, document the temporary safeguard, residual consequence and date by which the design will be reconsidered.
Operate from evidence
Monitor evaluation failures, bypasses, stale exceptions and resources that cannot be assessed. Version the policy engine and input schema because semantic changes can alter results even when rule text is unchanged. Give service owners enough context to correct a failure rather than encouraging blanket waivers.
Useful operational evidence includes policy revisions, test results, evaluation decisions, bypass grants, rollback events. Protect that evidence from routine administrators where practical, define how long it remains useful and make gaps visible. Measures such as resources evaluated, policy test coverage, exception age, failed or unknown evaluation rate should trigger a review, escalation or investment decision; a dashboard without an accountable response path is only decoration.
Prepare for failure and misuse
Prepare rollback for a policy release that denies production or unexpectedly permits exposure. Preserve the evaluated inputs and decision version so the event can be reconstructed. Emergency bypass should be time-limited, tightly scoped and visible to an independent reviewer.
Exercise a scenario that removes a trusted dependency or exposes an abused privilege. Require the team to use real contacts, alternate authority, preserved records and recovery procedures. Capture what was known, what remained uncertain and which decision changed the outcome. Improvements should be verified through a repeated technical check rather than closed when a document is approved.
Move from a pilot to sustained control
Begin with one representative service and complete the sequence: select one high-value guardrail, write intent and test cases, deploy in advisory mode, correct false decisions, enforce with rollback and monitoring. Publish the minimum standard, the exception route and the evidence required for acceptance. Expand only after the pilot shows that owners can operate the control without hidden manual work or unsafe workarounds.
Review the design after major platform, supplier, identity or business-process changes. Retire obsolete access and configuration rather than carrying every historical exception forward. Report progress in terms of reduced attack paths, faster verified recovery and clearer ownership. This keeps the programme connected to operating risk instead of measuring activity alone.
What to do next.
- ✓Separate policy intent from implementation detail.
- ✓Version rules, engine and schemas.
- ✓Test compliant and prohibited cases.
- ✓Stage advisory before enforcement.
- ✓Scope and expire exceptions.
- ✓Exercise rollback and emergency bypass.
Use guidance responsibly
Technology, provider behaviour and legal requirements change. Validate implementation details against current official documentation, test changes safely and obtain qualified legal advice where required.
Nandi Cele
AI & Application Security ContributorExamines secure AI adoption, application trust boundaries and practical safeguards for systems that can act on organisational data.
More from this writerLiam Khumalo
Secure Systems ContributorCovers software, SaaS and infrastructure design with an emphasis on maintainable controls, ownership and safe change.
More from this writerKabelo Nkosi
Infrastructure Assurance ContributorWrites about cloud foundations, cryptographic services, container platforms and resilient infrastructure operations.
More from this writer